Multimodal AI
AI systems that reason across multiple data types together — images, text, documents — rather than analyzing each in isolation.
Overview
AI systems that reason across multiple data types together — images, text, documents — rather than analyzing each in isolation.
The problem
Most AI tools are built around one input type, and disconnected single-input tools miss the context that comes from understanding image and text together.
Our solution
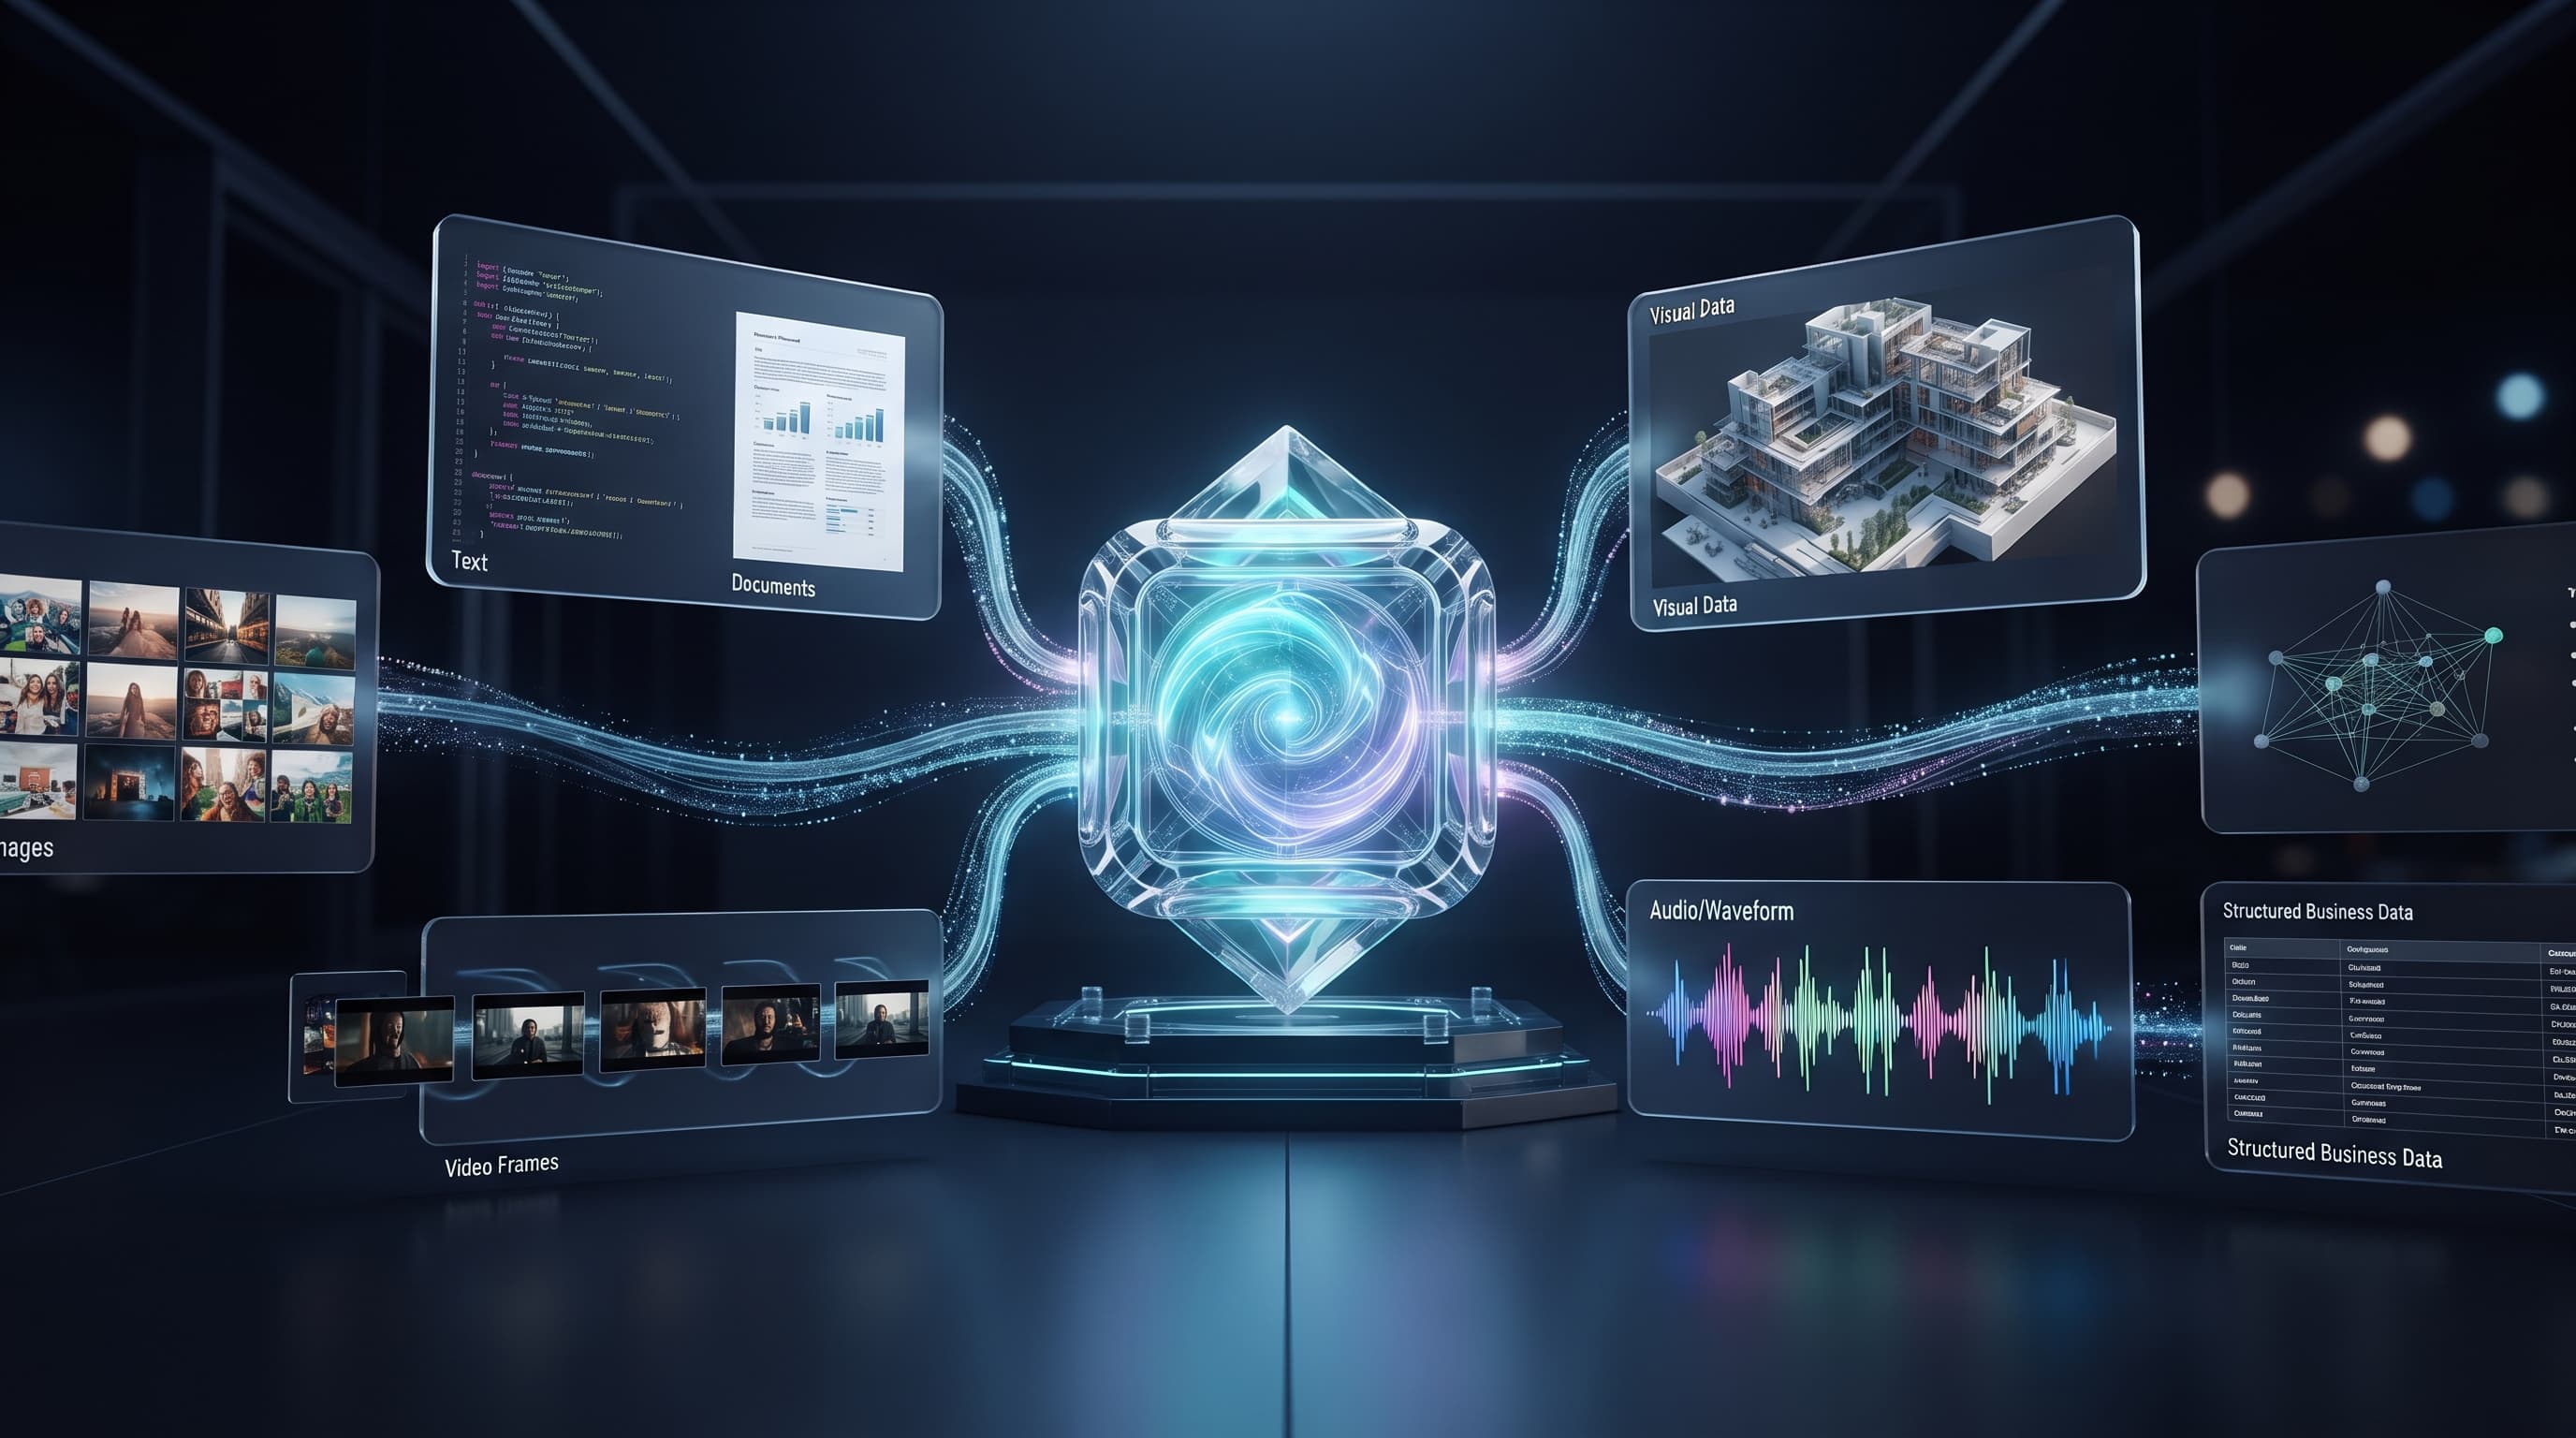
We pair vision and language components and fuse them into a shared representation, so the system can reason about an image in light of accompanying text, and vice versa.
Key capabilities
What we build.
How we build it
Our process.
Define Modalities & Use Case
Build Independent Encoders
Design Cross-Modal Fusion
Generate Structured Outputs
Evaluate Against Real Cases
Define Modalities & Use Case
Build Independent Encoders
Design Cross-Modal Fusion
Generate Structured Outputs
Evaluate Against Real Cases
Technology
Built with purpose-chosen tools.
Business value
Insight that a single-input model would miss, by reasoning across formats the way a person naturally would.
Use cases
- Document and image analysis together
- Visual question answering
- Multimodal search and retrieval
- Content moderation across formats
- Healthcare and technical imaging with context
FAQ
Common questions.
Most commonly images with text or structured documents, but the same fusion approach extends to other combined-input scenarios.
No — any business with both visual and textual information (inspection photos with reports, product images with descriptions) can benefit.