Document Automation
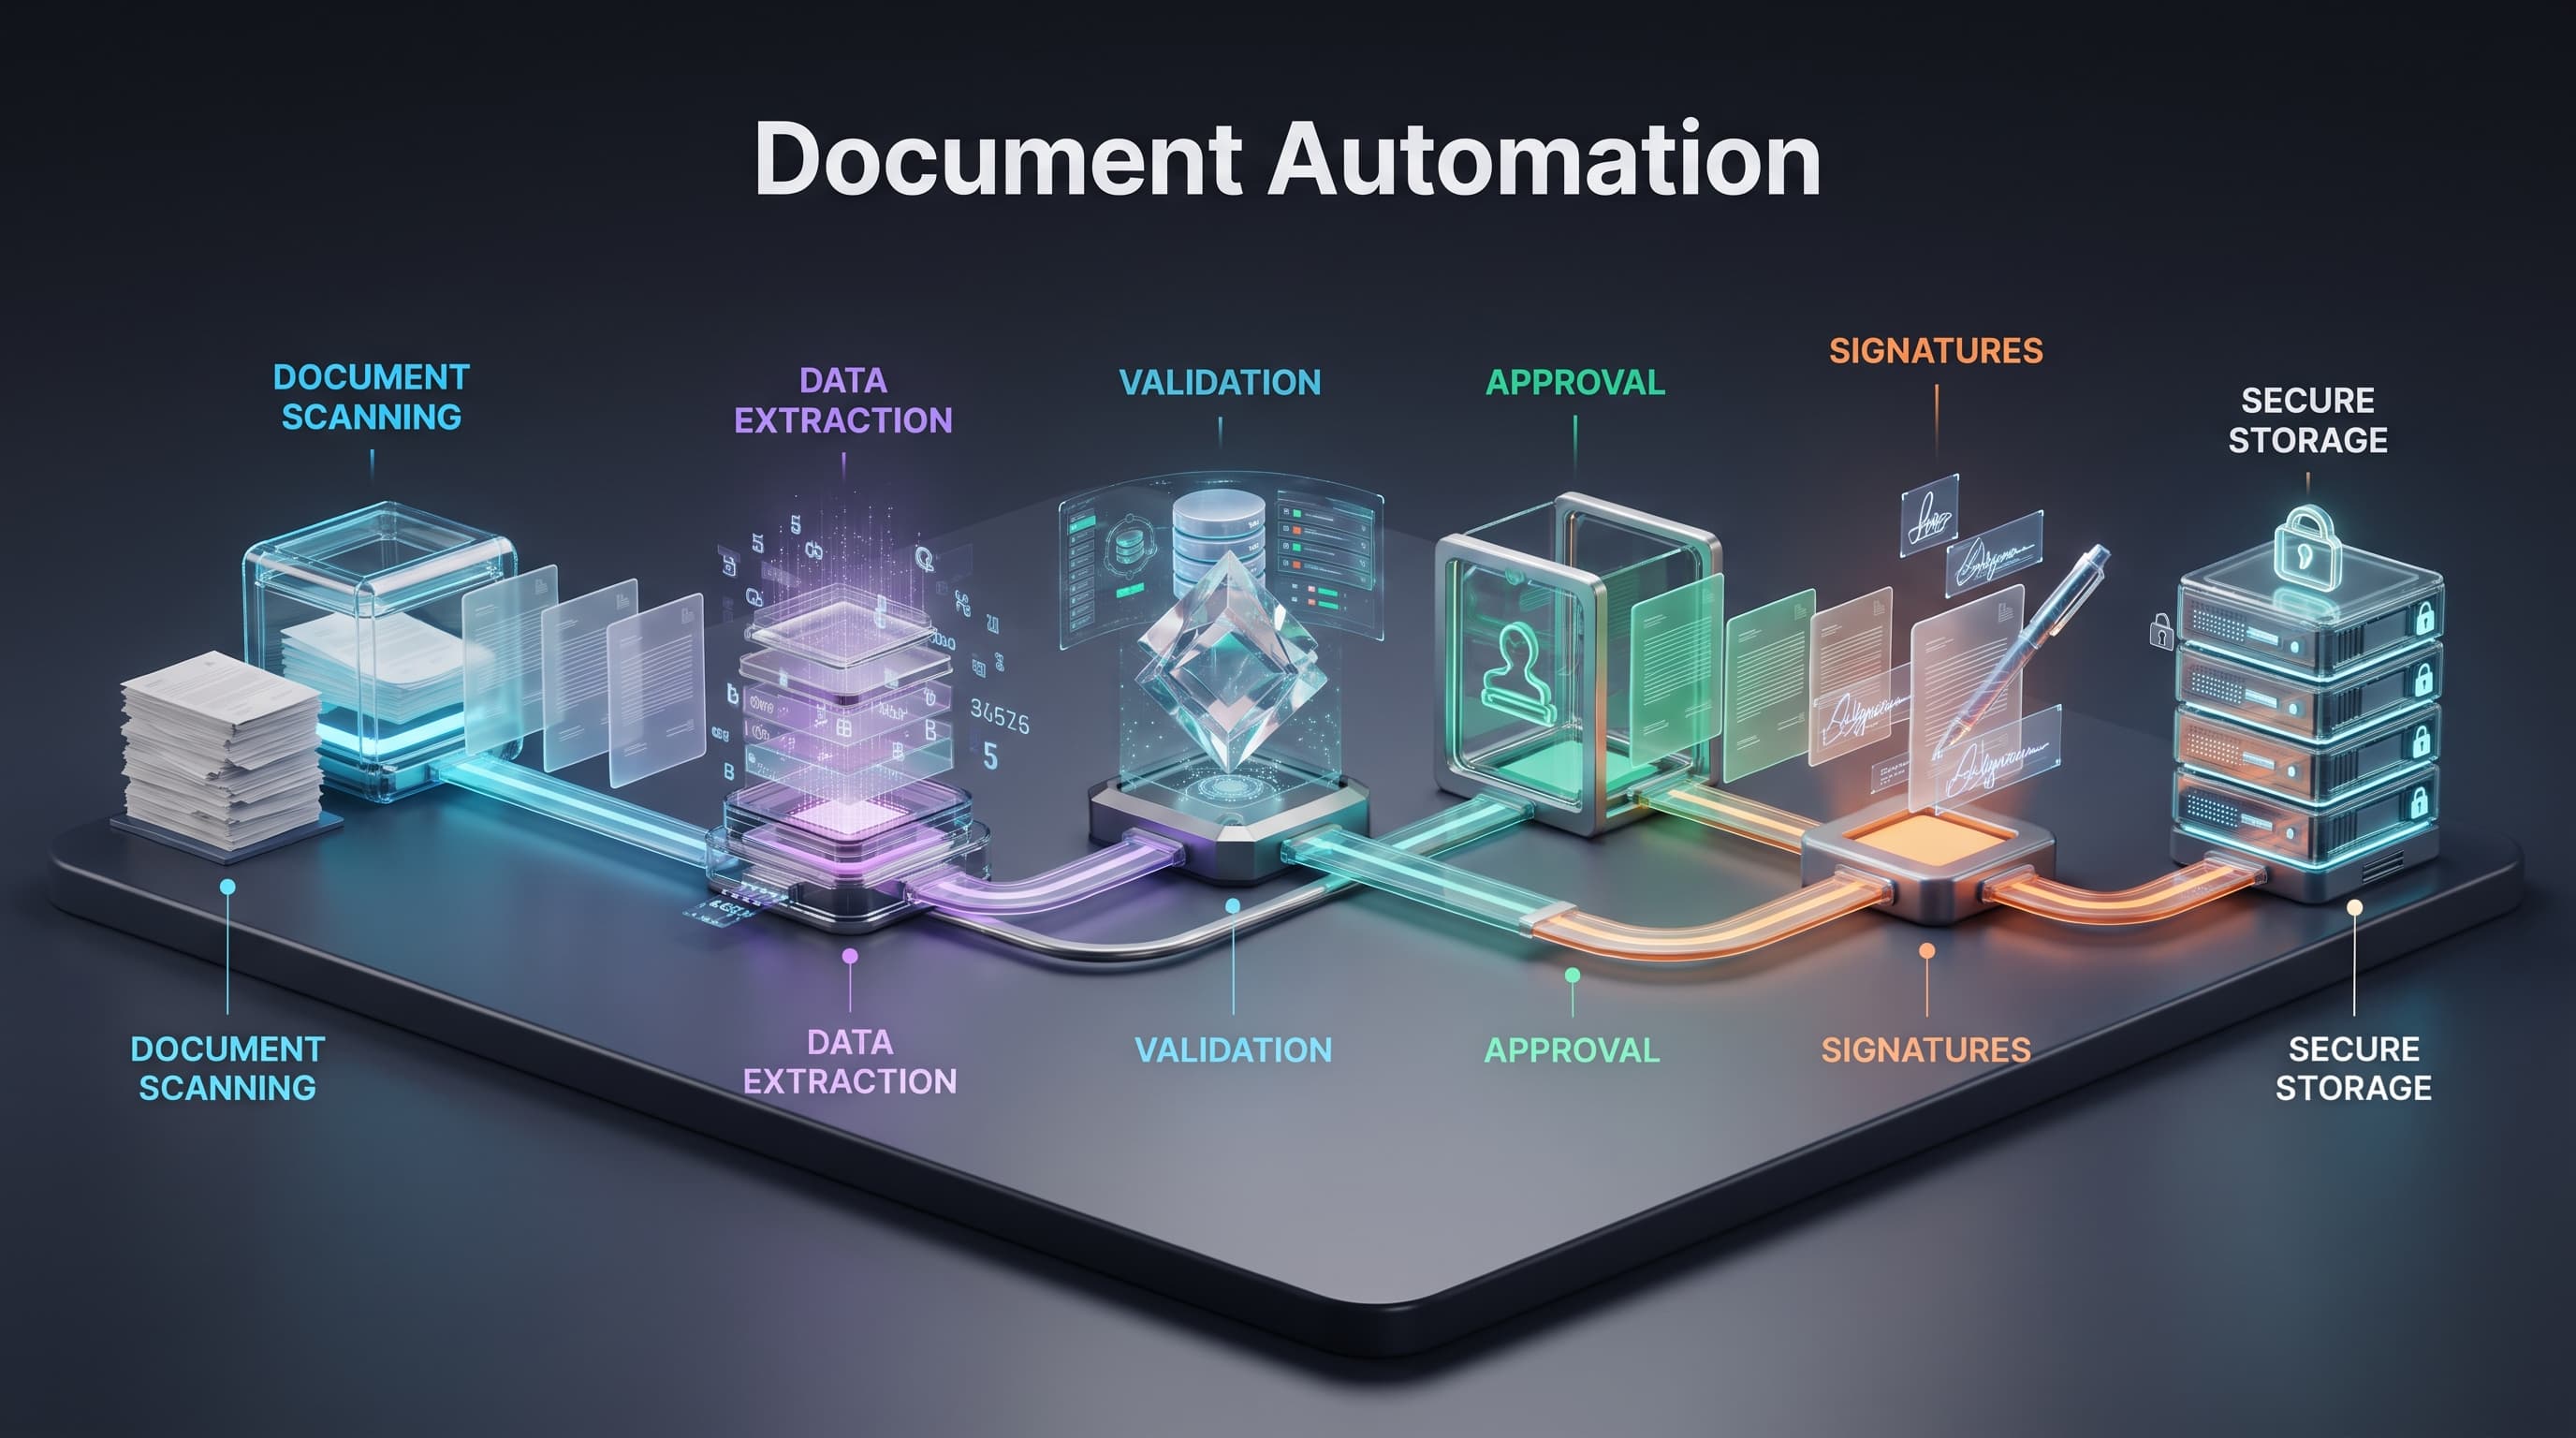
Systems that automatically process, classify and extract information from business documents — invoices, forms, contracts — without manual data entry.
Overview
Systems that automatically process, classify and extract information from business documents — invoices, forms, contracts — without manual data entry.
The problem
Manually reading and re-entering data from documents — invoices, forms, applications — is slow, repetitive and error-prone.
Our solution
We build pipelines that classify incoming documents and extract the structured fields relevant to each type, validating results before handoff.
Key capabilities
What we build.
How we build it
Our process.
Define Document Types & Fields
Build Classification Pipeline
Build Extraction & Validation
Integrate Into Workflow
Test Against Real Documents
Define Document Types & Fields
Build Classification Pipeline
Build Extraction & Validation
Integrate Into Workflow
Test Against Real Documents
Technology
Built with purpose-chosen tools.
Business value
Structured, validated data extracted automatically from documents, removing the manual re-typing step entirely.
Use cases
- Invoice and receipt processing
- Form and application processing
- Contract data extraction
- Automated document routing
FAQ
Common questions.
Most structured and semi-structured documents — invoices, forms, IDs, contracts — once we define the fields to extract for each type.
Extracted fields are validated against expected formats before handoff, with review flagged for anything uncertain.