Computer Vision for Real-World Business Applications
Computer vision projects tend to succeed or fail based on one thing more than any other: whether the system was built and tested against real-world capture conditions, or against a clean sample set that doesn't resemble what it will actually see in production. Here's what that distinction looks like in practice.
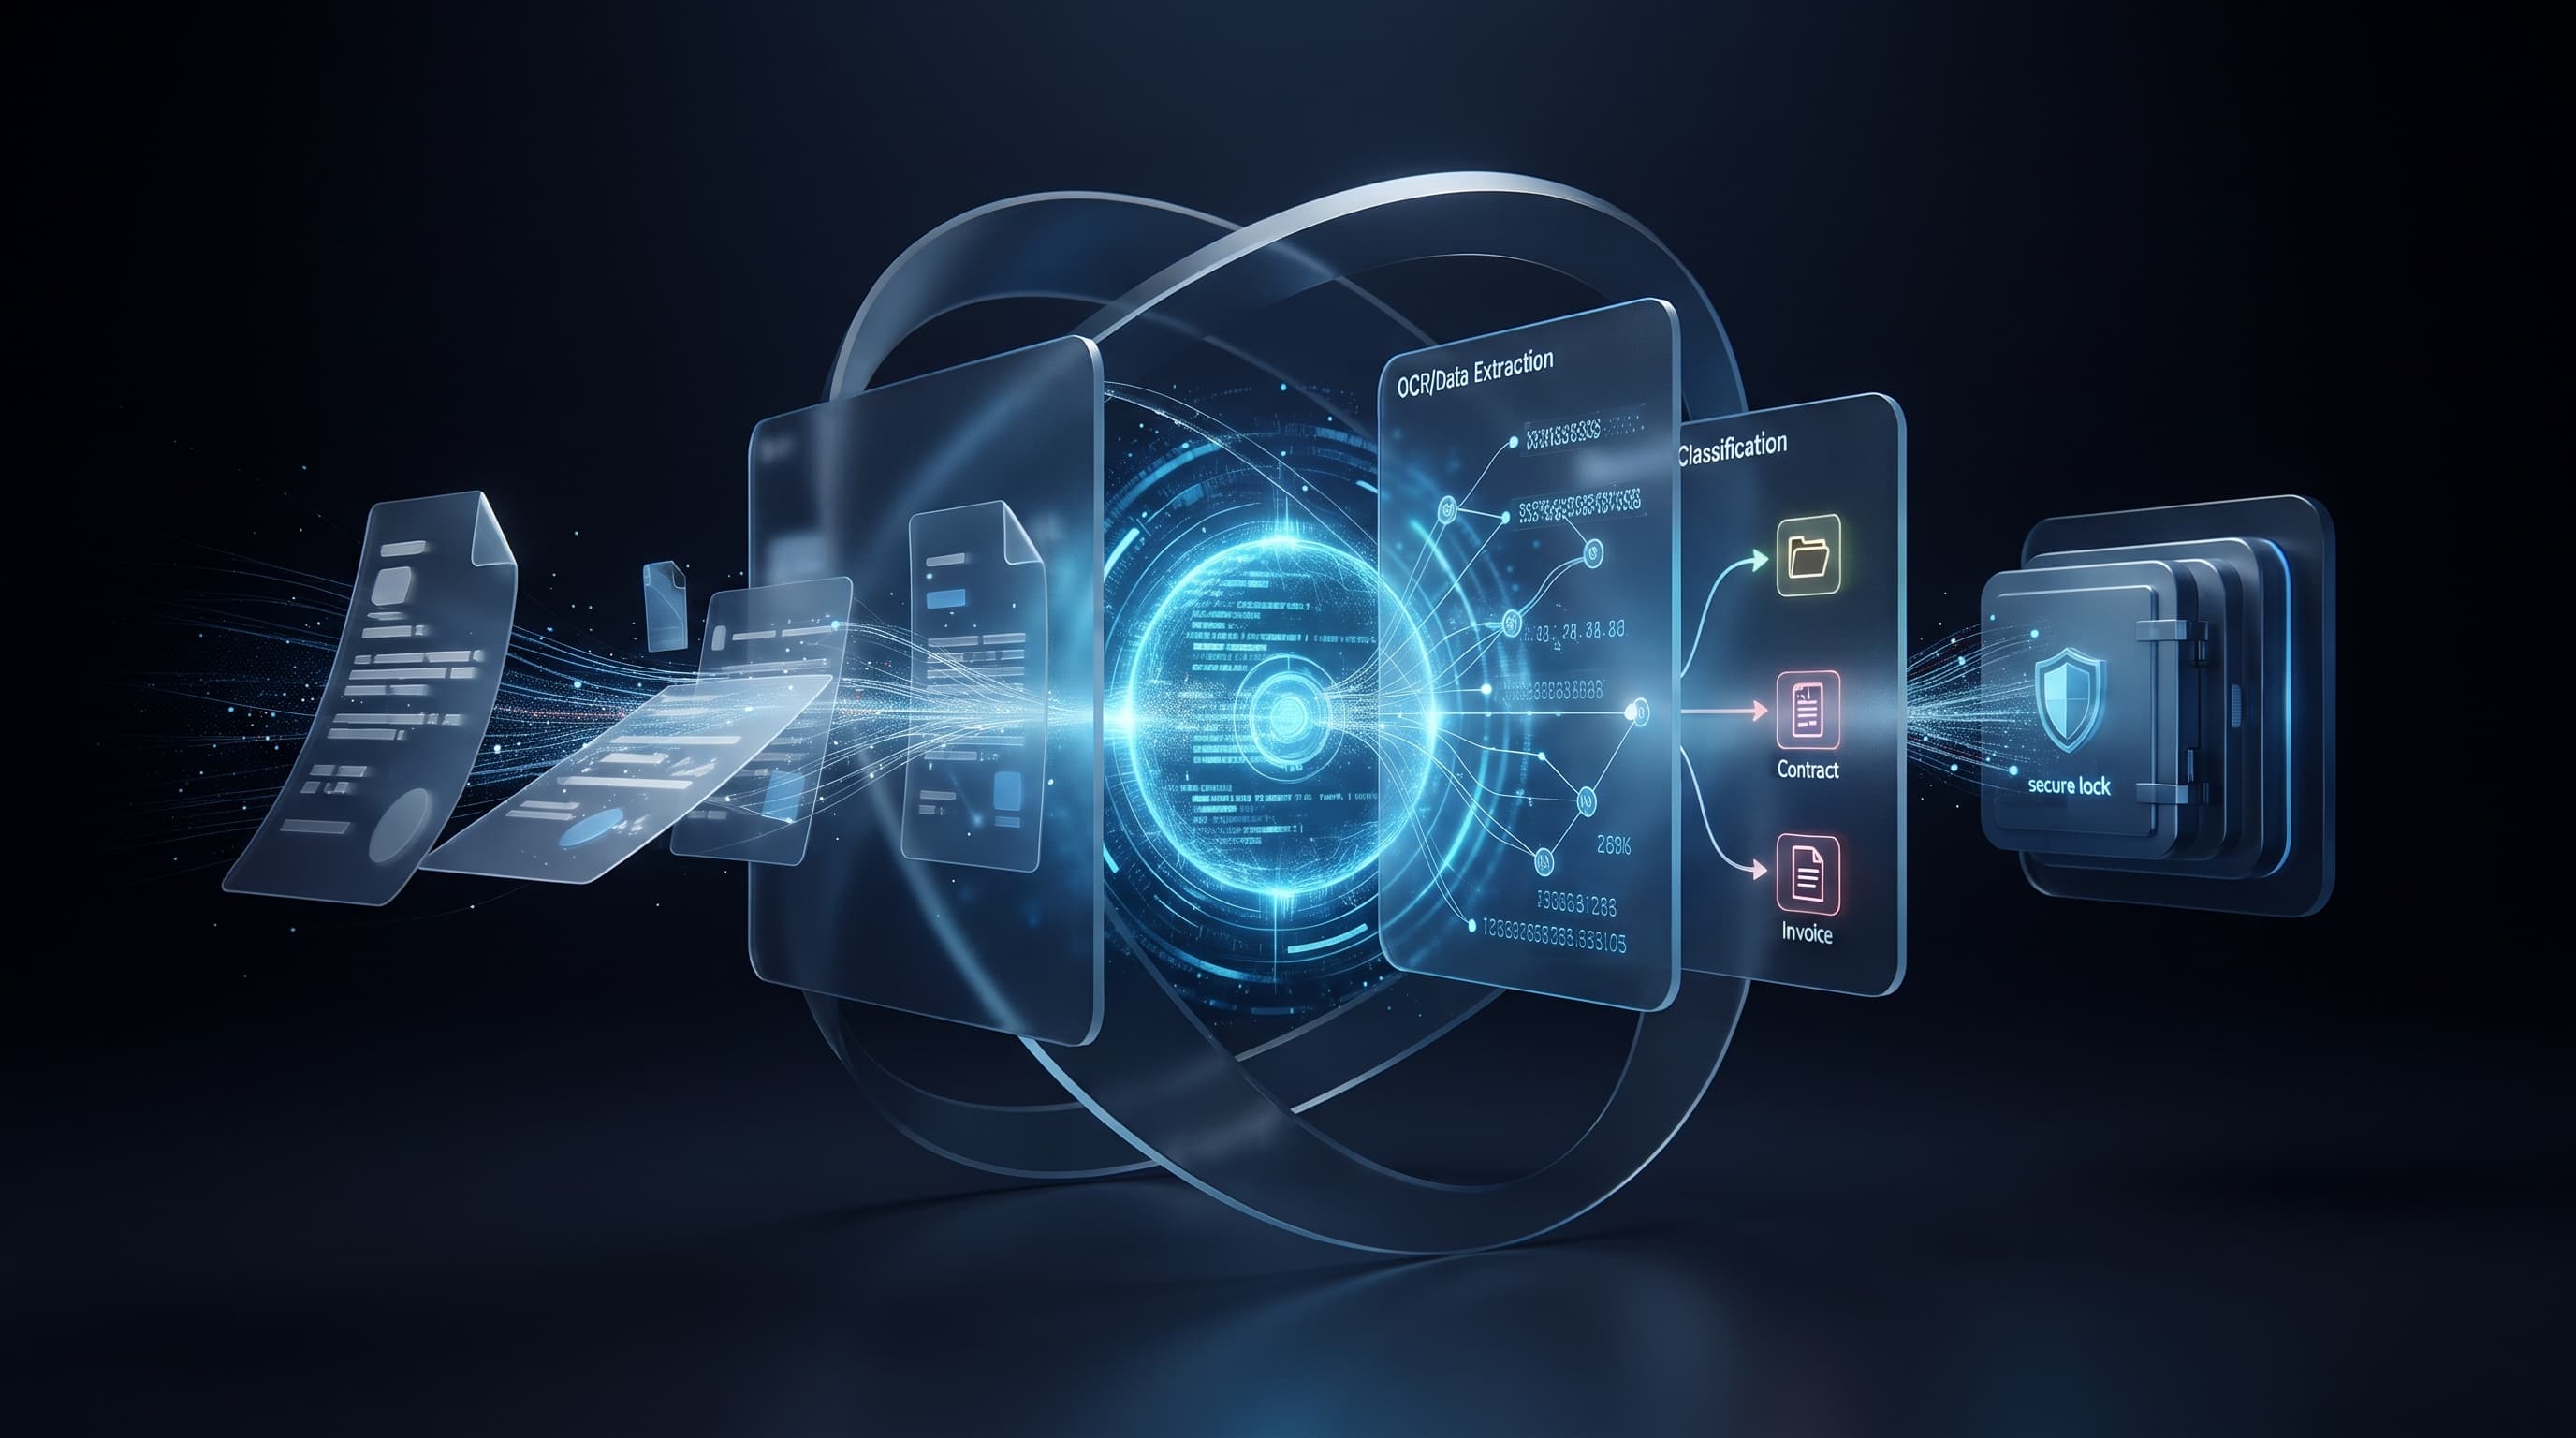
What computer vision does in a business context
In practice, business computer vision is about extracting structured information from images — documents, products, physical environments — that would otherwise require a person to manually review and record.
Why it matters
Manual visual review is slow and inconsistent between reviewers. Computer vision can standardize this at a pace and consistency people can't reliably match — but only when it's built for the actual problem, on the actual conditions the images will come from.
Architecture
Capture and pre-processing (cropping, deskewing, enhancement), a model layer suited to the task — classification, detection or OCR depending on what's actually needed — post-processing and validation of the model's output, and a human review path for anything the system isn't confident about.
Implementation approach
Start narrow — one document type, one product category — with a clearly defined output schema, and validate against real-world images from the actual capture conditions the system will face, not clean images gathered under lab conditions.
Common mistakes
- Training and testing only on clean, well-lit sample images that don't reflect real capture conditions.
- No confidence thresholding, so low-quality predictions get treated the same as high-confidence ones.
- Ignoring edge cases — damaged documents, unusual angles, partial occlusion — until they show up in production.
Production considerations
Latency matters for anything real-time. Low-confidence predictions should be flagged for human review rather than guessed at. And accuracy needs ongoing monitoring, because real-world input conditions drift over time in ways a one-time evaluation won't catch.
Security & reliability
Images frequently contain sensitive information — documents, faces, locations. Capture, storage and processing deserve the same care as any other sensitive data, not a lighter standard just because the data happens to be an image.
When to use it
High-volume visual tasks with a well-defined output, where manual review is the actual current bottleneck — not every task that happens to involve an image.
Business use cases
- Document capture and structured data extraction.
- Inventory and product recognition.
- Quality and condition inspection from captured images.
Key takeaways
- Validate against real-world capture conditions, not clean sample images.
- Confidence thresholding is what makes low-quality predictions safe to handle.
- Sensitive image data deserves the same security posture as any other sensitive data.
- Scope narrow first — one document type or product category with a defined output.
Keep reading